Most of AI is the data nobody wants to clean.
Two datasets built from nothing: a Lebanese Sign Language dataset recorded across Lebanon for OmniSign, and a training corpus distilled from real WhatsApp conversations for the Hader offline model.
- 50,000Signs collected for OmniSign
- 80,000+Samples after augmentation
- 1,160Conversations exported for Hader
- 863 / 169Train and held-out eval
From the first recording to the model
On OmniSign I worked on data collection with the team and integrated the trained model into the mobile app. On Hader I took the platform's own conversation trail and turned it into a clean, private, honest training set.
- Collection campaigns with Aaramoun Orphanage, Sin El Fil Church and SignWithNaila
- Landmarks per frame with MediaPipe Holistic, stored per signer and sign
- The trained sign model wired into the OmniSign mobile app
- PII scrubbing, de-duplication and format normalisation for the Hader corpus
- Train and eval splits checked for contamination
The pipeline
The same five stages on both projects, with very different raw material.
- 1Collect
- 2Scrub and de-duplicate
- 3Normalise to one shape
- 4Split train and eval
- 5Train
- 6Grade against a baseline
- 7Use it
OmniSign data
Raw campaign frames, and the model pipeline they feed.
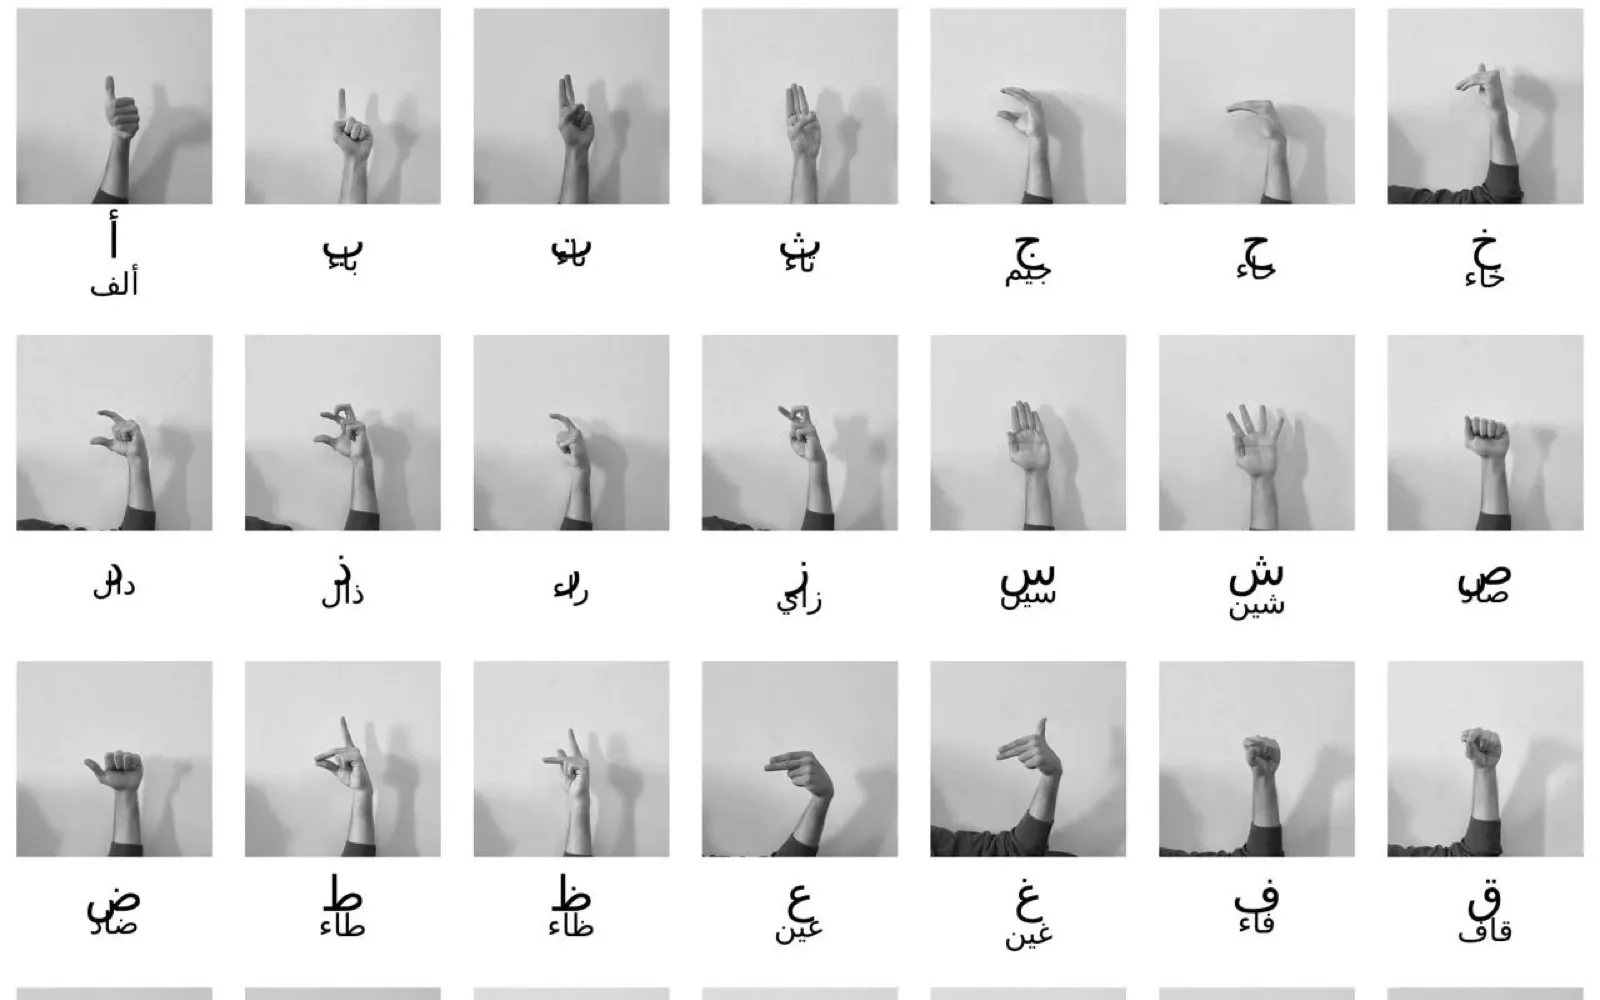
The Arabic alphabet in Lebanese Sign Language, one signer, raw frames 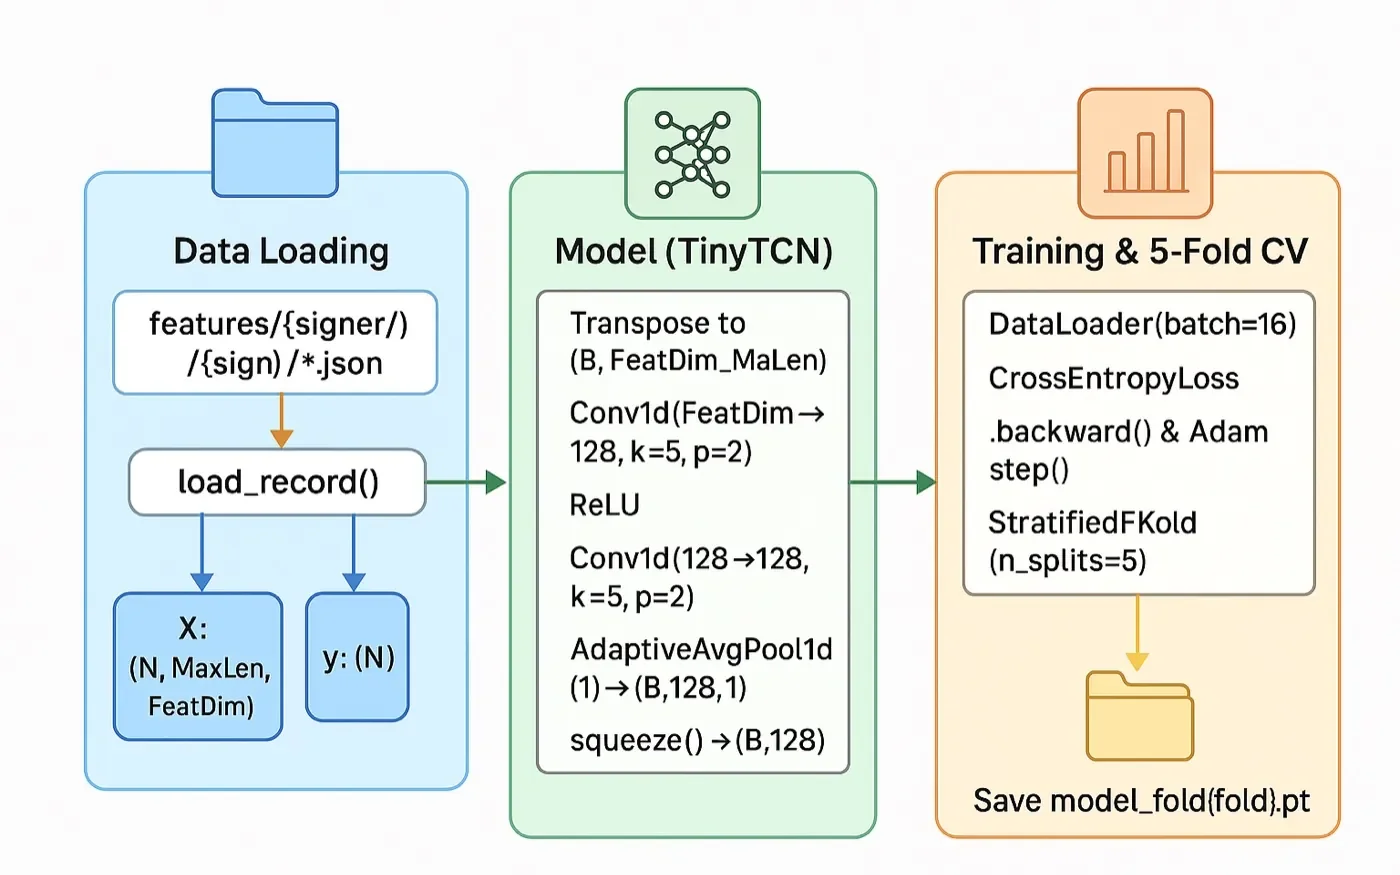
Load landmarks, a TinyTCN model, 5-fold training
What it does
- 01
Collected in the field
OmniSign signs were recorded in campaigns across Lebanon, because no Lebanese Sign Language dataset existed.
- 02
Landmarks, not pixels
Each sign is stored as hand and pose landmarks with joint angles, per signer and per sign, through a collection GUI.
- 03
Cleaned and augmented
50,000 collected signs became more than 80,000 samples covering the Arabic alphabet and around 30 daily expressions.
- 04
Private by construction
The Hader corpus scrubs names, phones, emails and locations with consistent placeholders, so grounding survives and nothing personal does. The raw export was shredded.
- 05
Normalised to one shape
Half the conversations repeated the incoming message in history, an old platform convention. Normalising every example cut duplication from 50.4% to 5.1%.
- 06
Honest splits
A time split still leaked FAQ-shaped questions into eval, five of 174. Fixed to zero, and the platform's own failure messages were removed as training targets.
Stack
- Sign data
- Python, PyQt5, MediaPipe Holistic, PyTorch, TFLite.
- Corpus
- Python scripts over Postgres, PII scrubber, 46-assertion test suite.
- Formats
- JSON landmarks per sign; JSONL chat examples.